

OpenAI has made its Decisions API generally available, doubling the limit to 400 questions per request. The October 22 release also adds prompt caching, native JSON input and inference residency in the US and EU.
The API uses GPT-6 Luna to classify text and images, route customer requests or select an agent’s next action from bounded answers.
Applications choose the form of the answer
The developer guide distinguishes three answer types. A predicate estimates whether a condition is true, such as whether a product photo shows damage.
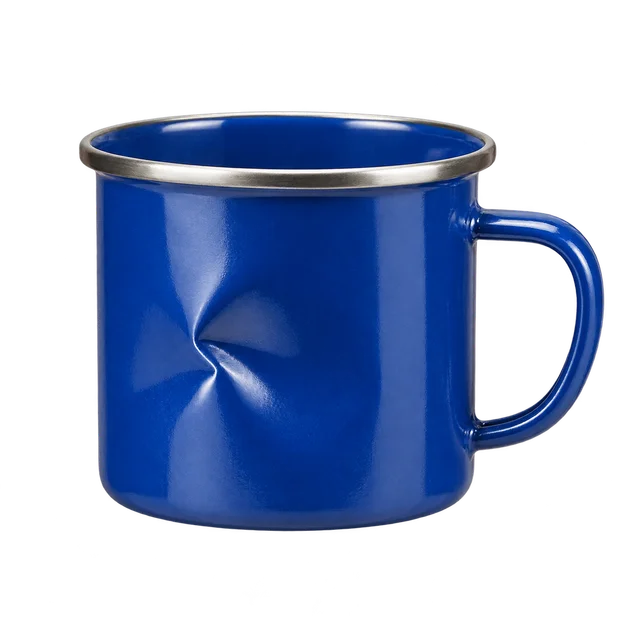
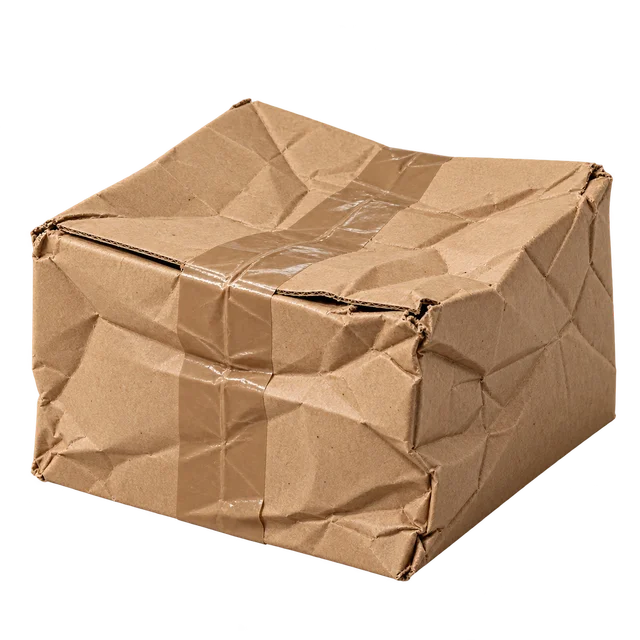
A choice selects a category, such as billing or shipping. Scores apply ordered levels, as in the guide’s package-damage example, which ranges from none to major.
Independent questions share one input. Questions that depend on earlier answers require separate requests, so a 400-question call evaluates shared evidence rather than running a sequence of dependent tasks.
Repeated context can qualify for caching
Prompt caching reuses an unchanged portion of the shared input, such as a reference document. The reusable prefix must contain at least 1,024 tokens; question text does not count toward that threshold.
The guide shows putting a reference image in shared input and each comparison image inside its question. That arrangement can reuse the reference while evaluating different candidates.
OpenAI lists uncached input at $0.10 per million tokens and cached input at $0.01 per million. Cache writes have separate charges, and regional processing premiums can apply; output tokens are not charged.
Source: OpenAI
Start the conversation by posting the first comment